Alibaba releases GUI-Owl-1.5 agent models from 2B to 32B under MIT
Alibaba’s Tongyi Lab published Mobile-Agent-v3.5 on February 15, 2026, describing GUI-Owl-1.5, a family of agent models that read a screenshot and emit the next tap, type or scroll. The family spans 2B, 4B, 8B, 32B and 235B-A22B parameters in instruct and reasoning variants, all built on Qwen3-VL. Every benchmark in the paper was run server-side against cloud sandboxes and emulators, and the authors give no on-device deployment, latency or hardware figures anywhere, so the small sizes are the only thing that points at a phone. The authors write that the smaller instruct variants, which skip the reasoning step, are fast enough to be deployed on edge devices and to work alongside a larger cloud model.
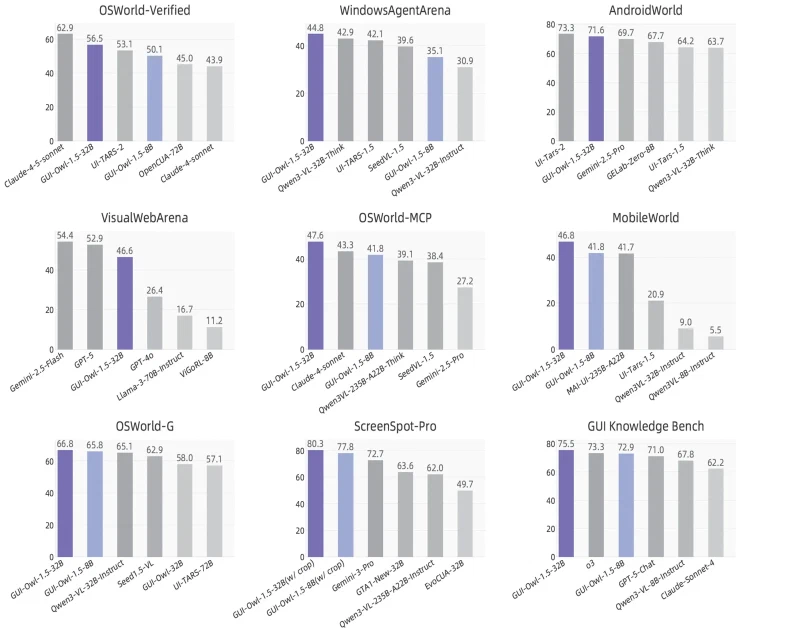
Across platforms, the authors report their 32B-Instruct model reaching 56.5 on OSWorld-Verified for desktop tasks, 47.6 on OSWorld-MCP and 46.8 on Mobile-World, the last two of which also require calling external tools. On AndroidWorld, which scores an agent driving real Android apps in an emulator, their 8B reasoning model reaches 71.6, which the paper puts just behind UI-TARS-2 at 73.3. For browsers, the paper’s table has the 32B reasoning model at 48.4 on WebArena, 46.6 on VisualWebArena and 82.1 on WebVoyager.
The small checkpoints carry a large part of that. The authors report 2B-Instruct at 43.5 on OSWorld-Verified and 67.9 on AndroidWorld, and 4B-Instruct at 48.2 and 69.8, which puts the 4B model within 2 points of their own 32B on Android tasks. On ScreenSpot-Pro, which tests whether a model can point at the right element in a high-resolution screenshot, they report 72.9 for 32B-Instruct and 80.3 when the model first crops a region and looks again. The paper’s prose and its tables disagree on which variant owns several headline numbers, and the figures above follow the tables.
Six checkpoints are on Hugging Face under the MIT license, covering 2B, 4B and 8B instruct, 8B reasoning, and 32B in both variants. The 235B-A22B model named in the paper is not among them. The code is MIT as well, and the repository points at a hosted cloud-sandbox demo rather than a local runtime.