Apple researchers run models twice the size of available DRAM from flash
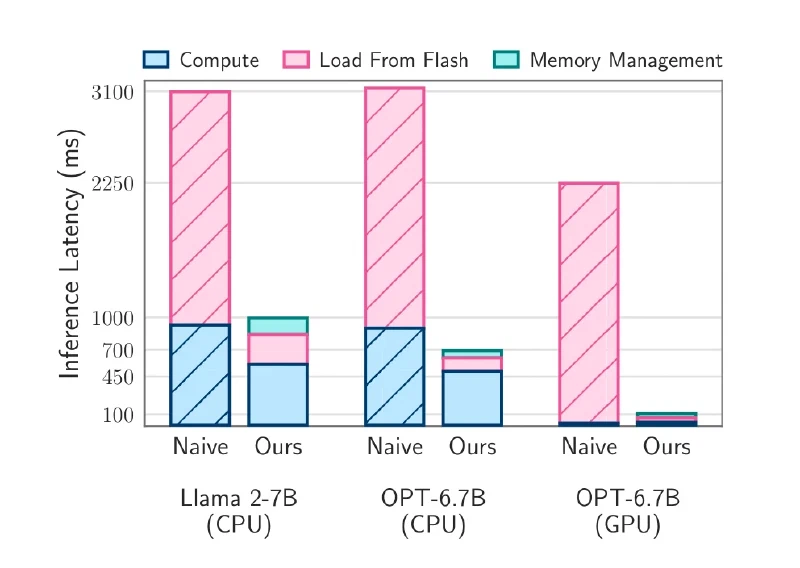
Apple researchers published LLM in a flash on December 12, 2023, a method for running language models that do not fit in a device’s memory. By keeping parameters in flash storage and loading them into DRAM only when needed, the paper reports running models up to twice the size of the available DRAM.
Two techniques carry the result. Windowing reuses neurons that were already loaded for recent tokens, which reduces how much data has to move. Row-column bundling arranges the weights so that reads follow the sequential access patterns flash memory handles best.
Measured against naive loading from flash, the authors report a 4 to 5 times increase in inference speed on CPU and a 20 to 25 times increase on GPU. The paper was last revised in July 2024.