Hugging Face publishes swift-transformers for Core ML models in Swift apps
Hugging Face published swift-transformers on August 8, 2023, the date of the repository’s first tag, a Swift package that gives iOS and Mac developers a transformers-like API for running language models on the device through Core ML. Pedro Cuenca introduced it as an in-development library built around four modules, Tokenizers, Hub, Generation and Models.
The Tokenizers module ports the normalisation and pre-processing rules that the Python tokenizers library keeps as configuration files next to a model on the Hub, so an app does not hardcode those decisions per model and can swap one checkpoint for another. It covered BPE at release, the family used by the GPT models, Falcon and Llama, with Unigram and WordPiece listed as later work. The Hub module downloads those configuration files and the model metadata, and Generation implements greedy decoding and top-k sampling.
The Models module wraps a converted Core ML package behind a LanguageModel type, and Core ML then decides whether to run it on the CPU, the GPU or the Neural Engine. Cuenca writes that flexible input shapes run on the CPU only, which is why Hugging Face’s exporters conversion tool switched to fixed sequence lengths, and that the Core ML path cached no attention keys and values at that point, both of which cap how long a context an app can work with.
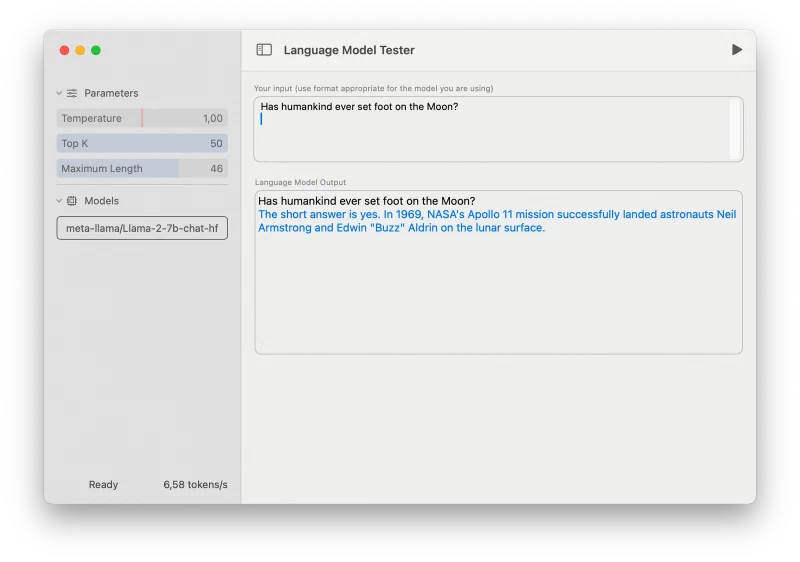
Hugging Face states it tested the package with Llama 2, Falcon, StarCoder and the GPT family including GPT2, distilgpt, GPT-NeoX and GPT-J, and that encoder-decoder models such as T5 and Flan were not supported. The release came alongside swift-chat, a Mac app that loads a Core ML model and doubles as a model tester, plus converted weights for Llama 2 7B and Falcon 7B on the Hub. The package is licensed under Apache 2.0.
This video could not be loaded. Use the link below to open it directly.