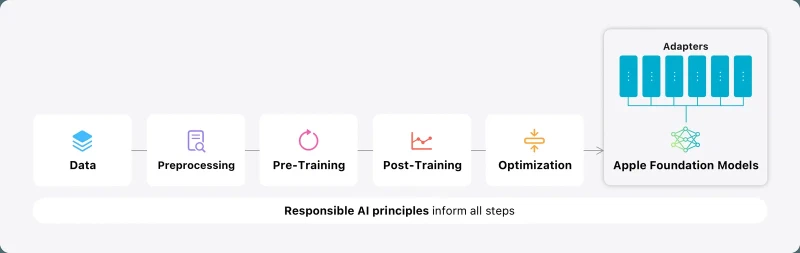
Apple Intelligence pairs a 3-billion-parameter on-device model with a server model
Apple introduced Apple Intelligence on June 10, 2024, built on a roughly 3-billion-parameter language model that runs on the device and a larger model that runs on Apple silicon servers through Private Cloud Compute. The on-device model uses a 49K token vocabulary, the server model 100K.
Apple compresses the on-device model with a mix of 2-bit and 4-bit weights, averaging 3.7 bits per weight, and says an option at 3.5 bits per weight costs no significant quality. On an iPhone 15 Pro the company reports a time to first token of about 0.6 milliseconds per prompt token and 30 tokens per second, both measured before token speculation.
Rather than ship a separate model per feature, Apple swaps LoRA adapters on top of the shared base model. The adapters are stored in 16 bits and, at rank 16, take tens of megabytes each. Apple says human graders preferred its models over comparable ones including GPT-3.5, GPT-4, Llama, Mistral and Gemma across its evaluations.