AMD trains its first small language model, AMD-Llama-135M, on MI250 accelerators
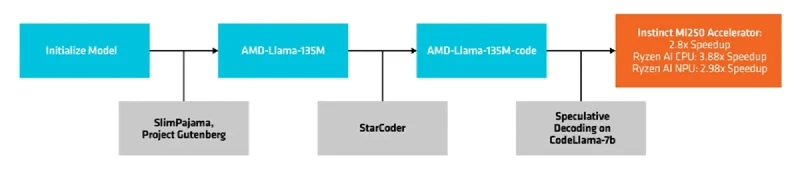
AMD released AMD-Llama-135M on September 27, 2024, its first small language model, at 135M parameters and trained from scratch on AMD’s own accelerators. AMD states that pretraining used 670B tokens drawn from SlimPajama and Project Gutenberg and took six days on four Instinct MI250 nodes holding four MI250 accelerators each. A second variant, AMD-Llama-135M-code, adds 20B tokens from the Python subset of StarCoder over another four days on the same hardware.
That code variant exists to work as a draft model for speculative decoding, where a small model guesses several tokens in one pass and a larger model then checks them, so the larger model can accept several tokens per forward pass rather than producing one at a time. AMD paired it with Meta’s CodeLlama-7b and measured throughput on the HumanEval coding benchmark. AMD reports about 2.8x higher throughput on an Instinct MI250 accelerator, about 3.88x on the CPU of a Ryzen AI processor, and about 2.98x with the 7B model running 4-bit on the Ryzen AI NPU while the draft model ran on the CPU, each against the same setup without speculative decoding. AMD’s footnotes name a Ryzen 9 PRO 7940HS as the test machine for the Ryzen AI numbers.
AMD published the weights on Hugging Face and the training, dataset and inference code on GitHub, under the Apache 2.0 license. AMD states the training code builds on TinyLlama and uses PyTorch FSDP for distributed training across nodes.